Projects language models

GPTune

Early GPT-2 fine-tuning tooling with practical presets for custom text generation.

Role
Creator and maintainer
Model
GPT-2, up to 774M parameters
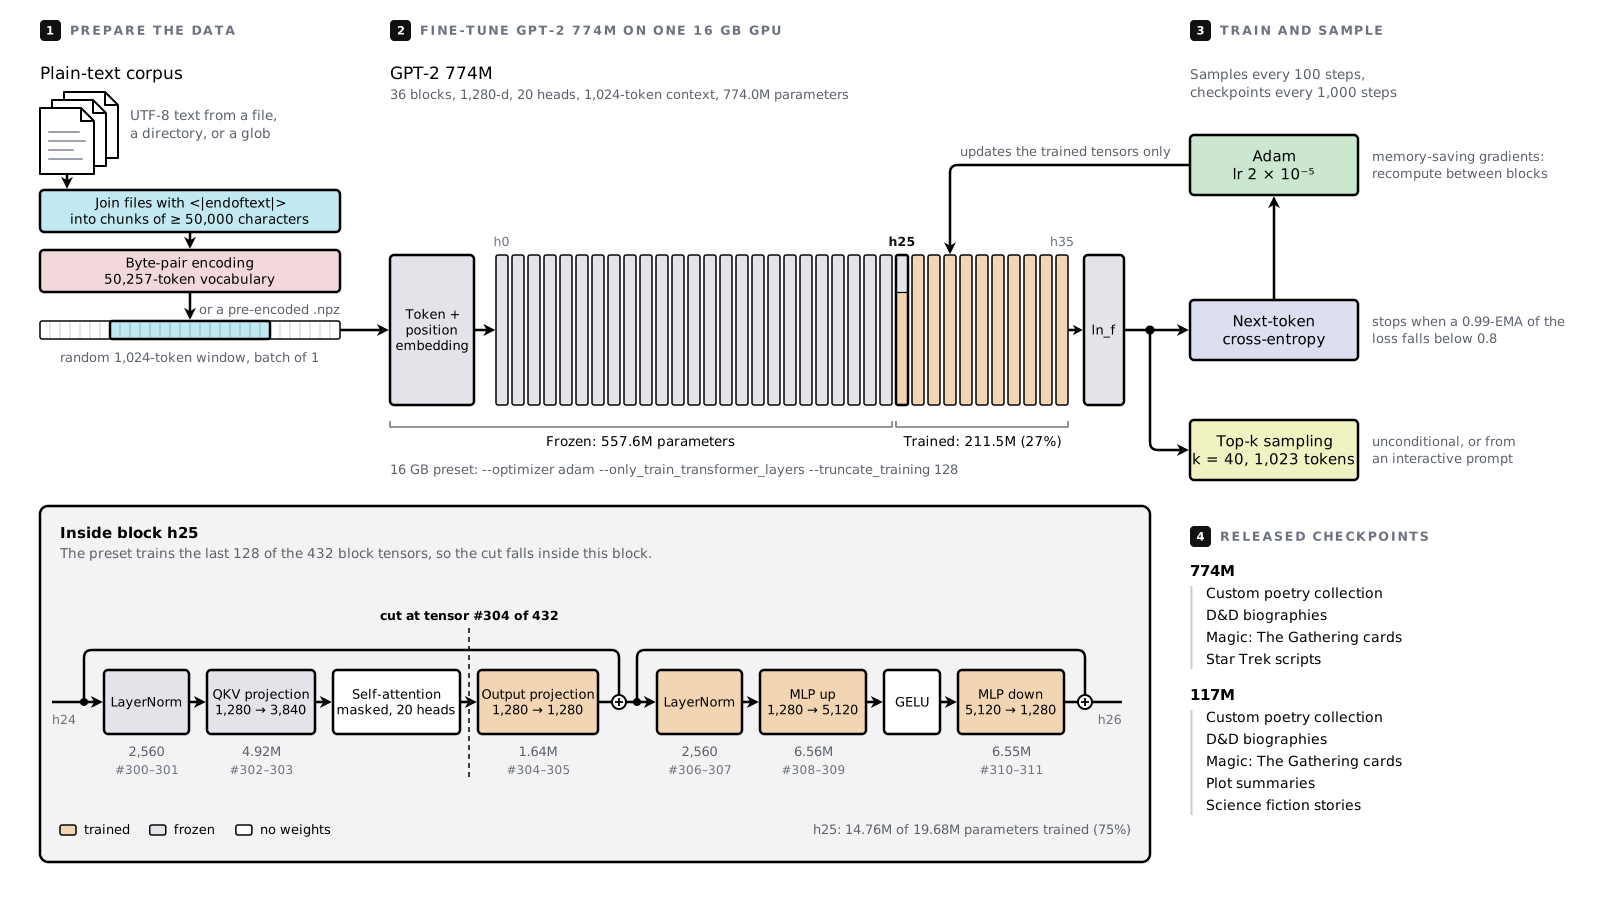
GPTune's 16 GB preset for GPT-2 774M: text files are joined, byte-pair encoded, and sampled as 1,024-token windows; the embeddings and blocks h0 to h24 stay frozen while the last 128 weight tensors, from inside block h25 to h35, are trained with Adam; a detail of block h25 shows where the cut falls; and the released 774M and 117M checkpoints are listed
What GPTune's 16 GB preset trains on GPT-2 774M. The preset updates only the last 128 of the model's 432 block tensors, 211.5M of 774.0M parameters, so the cut falls inside block h25. Parameter counts are computed from the model's hyperparameters and the variable order in the repository.

GPTune is an early GPT-2 fine-tuning repository built soon after OpenAI’s GPT-2 release. It packaged a practical command-line workflow for training and sampling custom text generators before today’s LLM tooling had become standardized.

The project demonstrates hands-on experience with large language model adaptation under the constraints of the time, including single-GPU training, dataset preparation, sampling modes, optimizer choices, and reproducible scripts for fine-tuning the 774M-parameter GPT-2 model.

Project details

Artifacts
GitHub implementation, training script, sampling modes, and fine-tuning presets
Keywords
  • GPT-2 fine-tuning
  • Language model adaptation
  • Custom text generation
  • Command-line tooling
  • Single-GPU training
  • Early LLM systems